Appearance
Lab 8 Prep Problems
Author: Daniel Zhang
Warning
Due: October 20th 2026, 2:00pm
Important
Click Use this template button (NOT fork) to create your repo based on it
Warning
Do not modify the provided debug preset in CMakePresets.json, as it may cause CI (GitHub Actions) failure. Add your own preset instead if you don't want to use the provided one.
Sprites
History (Optional)
Historically, video game systems faced multiple constraints which necessitated special hardware for handling rendering 2D bitmap images (sprites) to the screen. Specialized hardware support for sprite rendering is commonly known as hardware sprites. This section covers historical costs and limitations surrounding hardware sprites.
(Monetary) cost of memory
Consider that the Atari 2600 had a pixel display with a resolution of . Supposing we wanted to support 128 colours per pixel ( bits), we would need bits, or bytes. In 1977, 16KB of RAM could cost USD , which makes the cost of the memory for the screen alone USD.
Adjusted for inflation, this is approximately $5,300 USD ($7,200 CAD) in 2025. Clearly, it was infeasible to sell such a system as a household game console. Hence, it was either infeasible or costly to store entire framebuffers (a buffer of the entire screen's pixels) in memory. Instead, many early game systems only had enough memory to render on a scanline basis (one row of pixels at a time).
By using this optimization (along with others), the Atari 2600 shipped with only 128 bytes of RAM.
(Time) cost of computation
Even supposing we could store an entire framebuffer at a time, a purely software + framebuffer approach to sprites would mean having to erase each sprite from the last frame, and redrawing them in their new position on the current frame, before sending the framebuffer to the screen. Having the CPU handle this would mean eating up cycles not spent on actually running the game logic. Note that up until 2001 (with the IBM POWER4), computer processors were single-core (!)
With hardware sprites, classic gaming systems had dedicated hardware separate from the CPU which automatically composited (overlayed) sprites with CPU-configurable images and positions (and sometimes other transformations) onto a background. As the video chip processed a scanline, it would check which configured sprites intersected it and lookup the sprite pixel data accordingly, before sending the scanline to the screen. This frees up the CPU to focus on executing game logic, simulation, collision checking, etc..
Limitations of hardware sprite support
However, building dedicated hardware support means making tradeoffs between other limitations. Hardware sprites only supported limited number of sprites on the screen, and beyond that, limited (often strictly fewer) sprites per scanline. For example, the Atari 2600 only supported 5 sprites at a time, the NES supported 64 on a screen with only 8 per scanline, and even the 2004 Nintendo DS supported only 128 sprites at a time.
Supporting more sprites per scanline means increasing the time of checking the intersecting sprites per scanline, which at some point means not achieving the desired FPS. This is why sprites “flicker” on systems like the NES when 9 or more sprites show up on a line — programmers would implement sprite cycling to randomize which 8 sprites showed up on a given frame, so that the player could still see all 9 (but with flickering).
Other limitations included limited colours , maximum texture sizes as well as limitations on the types of transformations supported on the sprites. The NES and Sega Genesis both did not support zoom/scaling, and while all of the Atari 2600, NES, and Genesis supported various texturing mirroring, none of them supported arbitrary 2D rotations. The 1990 SNES supported arbitrary affine transforms only on the background. It wasn't until 3D support became commonplace in the 32-bit era that arbitrary affine transforms became widely supported on sprites.
Nowadays, memory is cheap (in 2025, a 64 GB DDR4 kit can be obtained for under $200 CAD), and we have powerful dedicated GPUs for parallel 3D processing and rendering. For this reason, we no longer need hardware sprites. We can easily store full-screen framebuffers in memory (A 1080p RGBA buffer with a byte per channel is only 8.3 MB), and we can effectively treat sprites as simple 3D geometry to send to our 3D hardware accelerators (GPU rasterizers and raytracers). In this lab, we will work towards building sprites in this modern paradigm — namely, 2D rendering is just treated as a special case of 3D rendering. Indeed, SFML is implemented on top of OpenGL, which just calls the 3D rasterizer on the GPU.
Sprites (TL;DR)
A sprite is a flat quad (represented as a coplanar set of 4 points in counterclockwise order), together with a texture. Because GPUs work fundamentally with triangles, each quad is cut diagonally and represented geometrically as two triangles. We can assign a point in a texture to any point in the quad by assigning “UV coordinates” (2D coordinates in texture space) to each of the 4 corner points, and interpolating in the texture space between the corners depending on the point in the quad.
To draw a sprite you send to the GPU vertex attribute data for each triangle (position, UV-coordinates), bind the appropriate texture, and issue a draw call.
In the following two sections we cover both the geometry and the texturing side in detail.
Geometry
A modern representation of sprites (indeed, almost any renderable object) has two main components:
- its geometry (and any transformations thereof), and
- its material (texture, colour, blending mode).
Here's a brief geometry primer.
Coordinate systems
In 2D, should the y-axis point up or down? Up is more geometrically intuitive with respect to the standard basis, and down makes sense if you think about how an image bitmap is laid out in memory (since row 0 is the top). In OpenGL, the viewport origin is at the bottom-left. In SFML, it is at the top-left. Similarly, for texture UV-coordinates (discussed in section Textures), SFML defines the origin to be the top-left, but OpenGL uses the bottom-left.
Finally, there is a matter of scale — SFML is designed such that the opposite screen corner to the origin is at point (and similarly for textures, texture width/height, though this can be configured to be in using sf::CoordinateType::Normalized). If you were to touch OpenGL, in fact you would think of the screen in the range .
To keep things simple we will adopt SFML's convention, but always be aware of the coordinate system you are working in!
Primitives
We assume a Euclidean setting. Informal definitions:
- Points: a point is a location in an underlying space. In -dimensional Euclidean space, it is often represented as a -tuple . In 2-dimensional Euclidean space, we can write .
- Vectors: a vector is a difference/displacement between two points. It can similarly be represented as a -tuple in -dimensional space . In 2D we may write .
If both points and vectors are represented in memory as -tuples, what's the difference? Semantically, one can subtract points to obtain a vector, and add a vector to a point to get a new point. But beyond that (and perhaps more tangibly), there are differences in how one applies transformations to them.
Transforms
You may recall from linear algebra that in the Euclidean setting, all linear transforms on vectors have a corresponding matrix such that . Recall furthermore that a transform is linear iff for all and for all .
It would be convenient if we could extend our linear algebra tools to include one of the most common transforms in video games — translations, so that we can make use of tools like matrix inverses and composition. Clearly, translation is not linear because, for example, . Thankfully, we have a useful fact — all affine transforms (composition of a linear transform and a translation) in -dimensional space can be represented as a linear transform on -dimensional space, using homogeneous coordinates.
Homogeneous coordinates
If you just care about doing the problems, the TL;DR of this section is — points and vectors are different things. In particular, points are affected by translation transformations, and vectors are not, because vectors are “points at infinity”. For example, suppose I had a struct like
struct Ray {
    Point2D position;
    Vector2D direction;
};
(which is just a directed line starting from some origin point). If I wanted to translate this ray, the translation should apply to the origin position, but not the direction (or else your ray would point in a different direction).
Points
The (canonical) homogeneous coordinates of a point in is the -tuple (e.g., in 2D, ). Furthermore, for any , we define the equivalence — that is, any two homogeneous coordinates which are just scalar multiples of each other represent the same underlying point. By convention, we normalize so that , i.e., . Without loss of generality, from now on we assume for all points.
Vectors
The homogeneous coordinates of a vector in is the -tuple . Note that by (informally) viewing this as , a vector is a “point at infinity” (thus truly just representing a direction, and not a point). Also, note that under this convention, adding a vector to a point yields a point, and subtracting two points yields a vector.
With our conventions on homogeneous coordinates for both points and vectors, we can always just store a point/vector in with floats (as opposed to ), since the last coordinate is always known.
Transformation matrices
For your own benefit only — not strictly needed for the problems.
Translation
The translation matrix which translates a point by the vector in 2D is given by
Which we can verify:
Scale
Furthermore, the scale matrix, which scales by and by (i.e., the Hadamard/element-wise product ) is given by:
which is again easily verified:
Rotation
Finally, the rotation matrix , which rotates points and vectors an angle of counterclockwise around the origin, is given by remapping the -basis vector to and the -basis vector to (verify for yourself that this is the case). Recall that the linear transform which remaps basis vectors just stacks the new basis vectors as column vectors side-by-side (you can easily verify this by multiplying with the standard basis vectors) — in this case, extending to homogeneous coordinates we get:
By composing these matrices, you obtain a transformation matrix for the composed transforms, and inverting the final matrix yields the composition of applying the inverse transforms in reverse order.
For your own understanding: By convention, a general affine transform object applies scale first, then rotation, then translation. What happens if we change the order of any of these? Why might the result be undesirable from a user perspective?
Another thing to consider is that the above verifications used points. Try for yourself what happens when you use vectors (whose last coordinate is 0) instead.
Important
Note. Affine transforms can be decomposed into a product of scale, rotations, translations, and shears (which we won't cover). Furthermore, in general an affine transformation matrix will always have a last row of . This means that in 2D you can represent typical (affine) transforms with just 6 floats (two for the new x-basis vector, two for the new y-basis vector, and two for a translation). Finally, transforms which have a final row which is different from the aforementioned are the more general projective transformations, which are out of scope for this course.
Triangles
A convex combination of points is the combination such that each and . Geometrically, a convex combination is a point which is “inbetween” the original points.
A triangle is the set of all convex combinations between three specific, ordered points . Furthermore, in graphics a triangle has a “front side” and a “back side”. The front side is defined (by convention) to be the side from which the sequence appears (“winds”) in counterclockwise order.
Triangles are the fundamental geometric building block for rasterizers. Triangle meshes (which are used to define the geometry of likely every character you have ever seen in a 3D video game) are so-called because they are just collections of triangles which approximate a true underlying surface. Why triangles and not quads? Triangles are the simplest possible polygon, and in particular, a non-degenerate triangle is guaranteed to identify a plane (i.e., its points are coplanar). This is not the case for a quad (e.g., take a square piece of paper and fold it along a diagonal).
For this reason, to define a quad, we use two coplanar triangles (e.g., one corresponding to the top-left of the quad, the other for the bottom-right).
Textures
Just like triangle meshes can be used to approximate arbitrarily detailed surfaces, we also need a way to approximate arbitrarily detailed images. In computers, this is achieved with raster bitmap images — the resolution of the bitmap defines the granularity of the approximation, and is proportional to the memory cost of storing the image.
In graphics, there are many types of images we might want to map over the surface of a triangle mesh. Color (albedo), transparency masks, normal/bump maps, specular maps, and emission maps, are some of the images we might want to display on surfaces to have fine-grained control of the appearance of meshes in a scene.
In our case, the sprite only requires a simple quad mesh of two triangles, but the question remains of how to “pin” specific points on the mesh to specific points in our texture space (called interchangeably texture or uv coordinates)?
The answer is: we associate each corner vertex of each triangle to a 2D UV-coordinate in texture space, and since each point in a triangle is a convex combination of its positions , we define its corresponding texture coordinate to be the same convex combination using the corner UV-coordinates:
The GPU rasterizer automatically handles calculating these in a perspective-correct way in 3D, so as a programmer your only job is making sure to set the correct texture coordinates for each vertex.
Texture interpolation
Generally, once the GPU obtains a -coordinate in texture space corresponding to in model space, and are typically not round numbers corresponding to exactly one pixel in the image buffer. Texture interpolation modes define how to define a “good enough” underlying continuous image given a discrete bitmap. A pixel stored at index [y][x] in the buffer corresponds to (i.e., the center of the pixel “square”).
Nearest neighbor: always chooses the single “closest” pixel to the coordinates. Best for pixel art games where “pixel perfect” results are needed, but looks blocky for medium/hi-res games. Fastest interpolation mode. Equivalent to viewing the underlying continuous image as piecewise constant.
Bilinear interpolation: Blends linearly from the 4 surrounding point samples. Best when a basic amount of “smoothness” is desired in the texture. Equivalent to viewing the underlying continuous image as piecewise linear.
For example, at , this corresponds to position relative to buffer indices, so the surrounding 4 pixels are at
img[y][x] = img[0][0], img[0][1], img[1][0], img[1][1]. Then in the x-direction and in the y-direction . First collapsing the x-direction, we gety0 = (1 - 0.1)*img[0][0] + 0.1*img[0][1]andy1 = (1 - 0.1)*img[1][0] + 0.1*img[1][1]and then collapsing along y, the final result is(1-0.8)*y0 + 0.8*y1.Bicubic interpolation: Fits a bicubic function to the surrounding 16 points. Smoothest, but slowest — details out of scope.
Blend modes
Supposing we have RGBA images (whether 3D rendered by our rasterizer, from an image editing software, or just from the web), the last question is how to composite them together.
In this section, we assume all RGBA channels are in .
Alpha compositing
Suppose we have a source image we want to composite on top of a destination image. If both images are fully opaque (have an alpha channel of 1), then trivially, the final image is . Suppose instead that the source image is semi-transparent (it has alpha values ). Then, default alpha “over” compositor (sf::BlendAlpha) is implemented as follows:
Clearly, this operation is non-commutative (swapping the order of the arguments changes the output). There exist many different blend modes that achieve different effects. For example, an additive blend mode is given by:
Problems
Suppose we use the rotation matrix for 2D space (represented again in homogeneous coordinates):
with the x-axis pointing right and the y-axis pointing down. Does increasing perform a clockwise, or counterclockwise rotation? What if the y-axis points up?
Designing a basic transform. Suppose we only wanted to support translations and scaling. In 2D, this reduces the degrees of freedom to just four dimensions — two for the scale and two for the translation. Here's one way to store such a transform:
struct BasicTransform {
    sf::Vector2f scale;
    sf::Vector2f translation;
};
Implement the following methods in
basic_transform.h(constis not indicated for you):A constructor taking custom scale and translation. It should have default arguments corresponding to the identity transformation.
sf::Vector2f applyPoint(const sf::Vector2f& p);which gives the result of applying the transform to a point. Both the input and output omit the last homogeneous coordinate.sf::Vector2f applyVector(const sf::Vector2f& p);which gives the result of applying the transform to a vector. Both the input and output omit the last homogeneous coordinate.As an aside, in production code one might have different classes for
VectorandPoint(not just aliases — overloads do not distinguish between those) such that you could defineoperator()()overloads onBasicTransformspecialized for taking each.bool operator==(const BasicTransform& other), which is just an exact comparison operator.
While the class of transformations spanned by either design is equivalent, think about whether it makes more sense to apply the scale or the translation first.
Assume we are in SFML's coordinate system with the y-axis pointing down and the origin at the top-left. Furthermore, the suppose the bottom-right of the screen is at point . Suppose we want a rectangle of width and height exactly half the screen dimensions, centered at the center of the screen.
List out, in counterclockwise order, 3 vertex positions for the triangle that is the top-left half of the quad, and then 3 vertex positions for the triangle that is the bottom-right half of the quad.
You should have duplicate vertex positions in (a). Using an index buffer (a buffer that stores indices into another buffer), propose a way to represent the above quad that does not duplicate vertex position information, and that uses less memory. Analyze, in terms of bytes, the memory usage of your new scheme vs in (a). You may assume that indices and floats are both 4 bytes. Consider when either approach wins (consider the number of times the same vertex is used by distinct triangles). Also consider if we used doubles (8 bytes) instead of floats.
Suppose we have assigned normalized UV coordinates to the 4 corners of the rectangle:
- top-left:
- bottom-left:
- bottom-right:
- top-right:
What are the (normalized) UV coordinates corresponding to the screen point ?
Sprite class. Complete the TODOs in
sprite.h, where the skeleton of aSpriteclass is provided. You will use asf::VertexArrayto represent the geometry and UV coordinates. It inherits fromsf::Drawable(and hence you can callwindow.draw(mVertexArray, renderStates)).A vertex array in SFML is just a thin wrapper around
std::vector<sf::Vertex>, together with asf::PrimitiveType. The latter determines how to interpret the list of vertices. For example,sf::PrimitiveType::Trianglesinterprets every 3 consecutive vertices as a triangle to be drawn.A
sf::Vertexis just a struct of 3 things:- a position in space (2D),
- texture coordinates for this vertex (2D) , and
- a color, as an alternative to texture coordinates (we will not be using this).
It is possible to use
sf::PrimitiveType::TriangleStripin this case, but for compatibility with a future lab, usesf::PrimitiveType::Trianglesfor this lab.You can reference a vertex array tutorial here.
The
Spritestores a raw pointer to its texture, which is assumed to outlive the sprite. It also stores amMinPointTexandmMaxPointTex, an AABB into the texture which represents the desired texture subrectangle for the sprite to use. By default this is just the whole texture, unless the special constructor with custom min/max point is called.Furthermore, an
mOriginrepresents the offset, relative tomMinPointTex, in texture coordinates, that the position of the sprite (stored in the transform) should be at in the texture.Finally we make use of our
BasicTransformto handle scaling and translations.We have provided a
mouse.cppfor you which has testing code. If you've implemented things correctly, you should see this: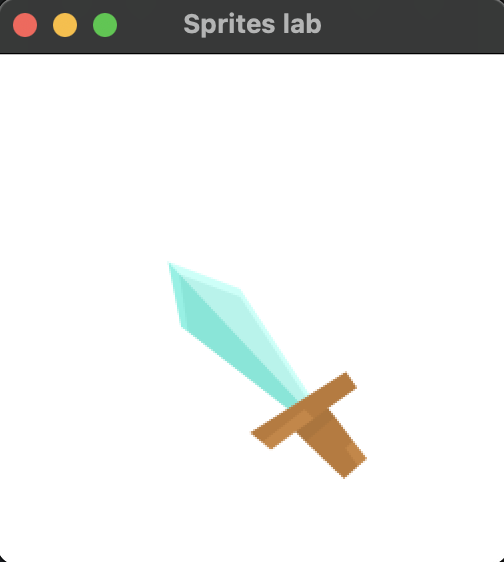
Figure 1
Completed prep for Sprite.
where the sword tracks your cursor. Your code should work the same regardless if you use the constructor line with
textureortexture2!
Barycentric Coordinates
Barycentric coordinates allow us to use 2D coordinates to parameterize the surface of a triangle, and they allow us to answer the question:
How do we find 2D coordinates given an arbitrary point in the triangle? (e.g., even if the triangle was in 3D space)
Since a triangle specified by corner points is convex, every point can be represented as a convex combination of the three corners:
where and . Because of the constraint , we have only 2 free parameters. Without loss of generality we will say is determined by : . Thus:
Important upshot: This formula has a simple geometric interpretation. Letting be a reference corner, is the vector from the reference corner to , and is the vector from the reference corner to . Then is just the reference corner plus some percent distance towards corner and plus some percent distance towards corner . are just those percentages.
If we represent in world space and similarly for the corners, we can write this in matrix form:
You should recognize this as a linear system in 2 variables. Assuming the triangle is not degenerate, is full rank and hence we can solve:
In practice, in 2D this system is solved with Cramer's rule. This is left as an exercise to the reader.
The render states also determine the blend mode and the used texture. See documentation: here.